Select Page

Verifiable Words for AI Agents: Putting Sema on Swarm

When two AI agents talk to each other, how do they know they mean the same thing? Over the summer we ran a proof of concept with the team behind Sema, a protocol that gives agents a shared, verifiable vocabulary, to find out whether Swarm can serve as one of the storage and distribution layers for that vocabulary. It can. This post explains what Sema is, what we tested, and where the collaboration might go next.

What Sema is, in plain terms

Agents coordinating across systems run into a quiet but serious problem: language is ambiguous. When one agent asks another to “lock the state safely”, there is no way to check that both sides picture the same procedure. Either they re-explain everything at length every time, which is slow and drifts, or they trust the label and hope, which fails silently.

Sema, created by Henrik Westerberg at Emergent Wisdom, solves this by making the word itself a proof. In its current implementation, every concept is written down as a Pattern Card: a small structured definition describing what the pattern does, what must stay true while it runs, what it depends on, and so on. The identity of the pattern is the cryptographic hash of those semantic fields. If two agents hold the same identifier, they hold, mathematically, the same definition. If anything in those fields changes, the identifier changes with it. There is no way to “mean something slightly different” under the same name.

On top of this, Sema provides a fail-closed handshake: before agents coordinate, each independently computes a single summary hash, called a root, over the patterns they intend to use, and they compare roots. Match, and they can proceed using short references. Mismatch, and they stop. The bootstrap library holds over 450 such patterns, spanning reasoning, coordination, data structures and protocols.

A useful consequence of this design is that Sema is storage-neutral. Because the meaning is verified by recomputing the hash, a vocabulary can be served by any store, honest or not, and the consumer always decides. That is exactly what made Swarm an interesting candidate: a censorship-resistant network that finds content by its hash is a natural home for content whose identity is already a content hash.

What we set out to prove

The question was never whether Swarm can hold files; it was whether Swarm can carry a Sema vocabulary release without weakening any of Sema’s guarantees, and whether Swarm’s own building blocks (feeds, file catalogues, access control) add real value rather than complexity.

We wrote a distribution specification together with the Sema maintainers, and defined a proof of concept with four workstreams and clear stop-or-go criteria. It ran against real Sema releases, the public Swarm gateway, and a real Swarm node.

What the POC showed

Sema identities survive the trip intact. We built an independent re-implementation of Sema’s hashing rules and recomputed the identity of every one of the 457 patterns in a full vocabulary release, plus both of its release roots. Every value matched the published ones, with 100% parity against Sema’s own reference implementation, including tricky edge cases in how numbers and Unicode are normalised. A shared set of test cases that both implementations agree on came out of this as a by-product.

Anyone can fetch a release from Swarm and check it for themselves. As a test, we published a complete Sema vocabulary release — all 457 patterns — through a public Swarm gateway, then retrieved it the way an ordinary user would: from a web address, with no node to run, no wallet and no keys. Nothing about the transfer had to be trusted, because everything that arrived was re-checked locally against Sema’s own rules: every pattern identity and both release roots, recomputed from scratch. We also tried to break it — a pattern edited with its checksum patched up to match, a pattern quietly left out of the release, a single flipped byte, a forged root — and every attempt was caught and rejected. The loop has since closed with no special tooling at all: a standard, unmodified Sema client installed a complete release from a web address, recomputing every identity and both roots from scratch before we switched over to it.

A small change should cost a small update. Because a Sema pattern’s identity includes the identities of the patterns it builds on, one edit can ripple far: between two consecutive vocabulary releases, one of them a broad quality pass over the vocabulary, 94% of the patterns received a new identity, including well over a hundred that nobody had touched directly. If publishing and syncing had to re-send the whole library each time, that ripple would be expensive. The specification is built so that cost follows what was actually changed, and on that real release pair the POC measured exactly that: patterns whose identity changed only through the ripple cost nothing extra to re-send.

Swarm makes those updates cheap. The most open question going in was whether the way Swarm organises files into a catalogue would live up to that promise in practice. Measured against a real Swarm node, updating a single pattern in the catalogue cost the publisher about 6 KB of uploads and a consumer about 12 KB of reads — between 19 and 234 times less than the three republishing routes we measured. A consumer on an older release could also work out exactly what changed between two releases by comparing the two release catalogues, without downloading a single pattern. Even on the 94%-churn pair, part of the previous release could be reused as-is.

Verdict: every trust guarantee Sema makes locally held up end-to-end over Swarm, on real data and a real public gateway, and Swarm’s efficiency layer earned its place, with the conditions it needs to stay predictable now written into the specification.

Where this could go

None of this is committed; these are phases sketched in the specification, to be sequenced with the Sema team.

The nearest step needs no Sema-side code: publish each release to Swarm alongside its Git-hosted one, installable by any current client from an open public gateway URL. Dual-publishing could then become part of the normal release process, with a release-signing scheme (proposed, still under review), a feed pointing always at the latest release, and delta sync for consumers several releases behind. Further out are the things a conventional host cannot do at all: an open channel where any agent can announce a new pattern for curation, forks that stay easy to compare, and private registries for vocabularies shared within a closed group — the same ground as our broader work on Data-Enriched AI Marketplaces, where verified vocabularies, agent identities and machine-to-machine payments meet on the same network.

Throughout, Sema stays storage-neutral by design and Swarm would be one distribution layer among several. Optional does not mean interchangeable, though. A conventional host asks to be trusted; Swarm does not, because content is addressed by its hash and re-checked on arrival — the same assumption Sema already makes about meaning, extended to the storage layer. Add updates that cost what the change costs, and Swarm looks less like an alternative file host than a match for the way Sema already works.

Learn more

  • Sema: semahash.org, and the paper “Sema: When the Hash Is the Word” (10.5281/zenodo.19462702).
  • Interested in distributing verifiable content over Swarm? Get in touch with us.
Unlocking the AI-Driven Health Data Economy: Your Health, Your Data, Your Equity

Unlocking the AI-Driven Health Data Economy: Your Health, Your Data, Your Equity

Imagine turning your daily health metrics—from fitness wearables to electronic medical records—into a secure, recurring income stream without ever giving up ownership or privacy. This is the core vision of the AI-Driven Health Data Economy, a new paradigm that connects individual wellness trackers data and data gathered in public and private health systems with recent advances in AI and Web3. Instead of allowing centralized tech giants and data brokers to profit from your sensitive information, this emerging ecosystem aims to return the financial upside directly to individuals, enabling them to maintain total sovereignty over their health history while participating in an open network that accelerates global clinical research.

For individual data contributors and health DAOs, the concept relies on automated AI agents and smart contracts to create frictionless Data-Enriched AI Marketplaces. When you securely share access to your records through a personal Swarm Health Data Wallet, the DAO curates and logs your contribution directly into a transparent shared pool contract. Rather than issuing a static receipt, a published formula evaluates your data’s value—based on factors such as rarity or completeness—and assigns a validated weight. Crucially, the buyer’s payment flows directly into this contract rather than the DAO’s wallet, helping ensure transparent and proportional compensation.

Autonomous AI agents on behalf of the DAO then aggregate these anonymized data pools and license them to biotech firms and medical researchers. The moment a transaction clears, the smart contract automatically distributes the revenue back to individual data contributors, entirely bypassing the corporate middlemen who usually capture the profits.

In this proposed model, a public, unalterable formula evaluates each contribution based on its real merit so that everyone is paid exactly what their data is worth. 

Introducing the Access Control Trie (ACT) in Swarm

Introducing the Access Control Trie (ACT) in Swarm

by András Arányi

The Access Control Trie (ACT) is an essential feature designed to manage access control in Swarm’s decentralized storage infrastructure. It enables publishers to grant or revoke access to specific content at the chunk level using encrypted session keys. This guide will walk you through the key concepts and practical aspects of using ACT to protect your data in Swarm.

If you’re a content publisher and looking for a way to share data but maintain full control and privacy, you might find that the below concept of a fully fledged access control mechanism covers all your needs.

Content Publishers

⚠️ TLDR: Publishers can control access to their data by encrypting access keys for each viewer and adding/removing them from the ACT lookup table. ⚠️

As a publisher, you have full control over who can view your content. Using ACT, you can upload your data and grant access to specific grantees (viewers) by referring to their Swarm node wallets’ public keys. Additionally, you can revoke access at any time, ensuring that only authorized viewers have the ability to access your data.

What makes ACT unique is that, as opposed to other solutions which only encrypt data, ACT ensures that only the intended viewers will have access to the data. Everyone else is blocked, even from discovering an encrypted version of it. This significantly increases the privacy and security of your content, preventing unauthorized users from knowing the data even exists.

How to manage access:

  1. Upload your content to Swarm as you normally would, but with ACT request headers included.
  2. Assign access rights by adding the grantee’s public key to the ACT.
  3. If needed, revoke access by removing the grantee from the ACT.

Keep in mind: Publishers can control the latest version of content that grantees are able to access. If you update your content, viewers might still have access to an older version if they were granted access to that earlier version before.

You can learn more about how to manage access using tools like swarm-cli by following the tutorial in the Swarm documentation. These features are also fully supported by the Bee API (starting from version 7.0+), enabling any application to interact with them directly.

Grantees (Content Viewers)

⚠️ TLDR: Grantees can access the specific version of content that the publisher has granted access to, but may lose access to future versions if revoked. ⚠️

As a grantee, your ability to view the content is based on the public key of your Swarm node’s wallet and depends on the permission granted by the publisher. The process for gaining access is simple and secure, thanks to ACT’s encryption mechanisms.

How it works:

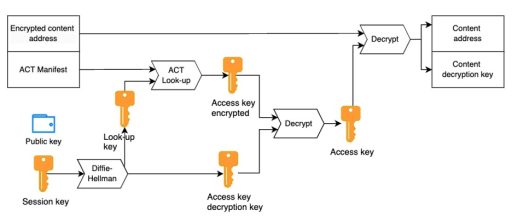
  • Your Swarm node wallet’s public key is used as a session key, which is then used to create two additional keys:
    • A lookup key to find your entry in the ACT lookup table.
    • An access key decryption key, allowing you to decrypt the content access key specifically encrypted for you.

This ensures that only you can decrypt the content, and you can retrieve the version of the content you have (or have had) permission for.

How ACT Manages Grantee Access

ACT employs a sophisticated mechanism to manage grantee access using public-key cryptography and secure key derivation. At the heart of this system is the ACT lookup table, a key-value store that securely links each grantee’s Swarm node wallet’s public key to an encrypted access key. Here’s a breakdown of how it works:

  1. Session Key:
    Each grantee’s Swarm node’s public and private key pair serves as their unique session key. This session key is crucial because it forms the basis for all further encryption steps related to the grantee’s access.
  2. Key Derivation via Diffie-Hellman:
    Using Diffie-Hellman key derivation, the session key is used to derive two important keys:
    • Lookup Key: This key is used to identify the specific entry for a grantee in the ACT lookup table.
    • Access Key Decryption Key: This key is used to decrypt the access key, which in turn allows the grantee to unlock the protected content.
  3. Encrypted Access Keys:
    The content access key is encrypted specifically for each grantee using their derived decryption key. This ensures that only the intended grantee can decrypt the access key and thus view the content. This per-grantee encryption adds a layer of security, preventing unauthorized access even if someone else obtains the encrypted data.
  4. ACT Lookup Table:
    The lookup table itself is implemented as a key-value store within a Swarm manifest. Each grantee’s public key maps to an encrypted access key, ensuring that only authorized users with the correct session and decryption keys can retrieve the access key and, subsequently, the content. This table allows publishers to manage access dynamically, adding or removing grantees as needed without compromising the security of the stored content.
  5. Adding and Removing Grantees:
    Publishers have the flexibility to dynamically add or remove grantees from the lookup table. When a grantee is added, their public key and the corresponding encrypted access key are stored in the lookup table.

Version Control and Historical Access:
The ACT maintains a version history, which includes timestamps for each version of the access control list. If a grantee’s access is revoked for new versions of the content, they can still access older versions to which they had been granted permission, based on the relevant timestamps.

Encryption and Security in ACT

⚠️ TLDR: Every element in the ACT process is encrypted, ensuring complete security of content and access control. ⚠️

As demonstrated earlier, encryption is central to how ACT is implemented. Every component, from the grantee list to the content access keys, is encrypted using strong cryptographic methods. This ensures that only authorized users can access your data, and any tampering or unauthorized access is effectively prevented.

Here’s how encryption is applied:

  • Grantee List Encryption:
    The list of grantees is encrypted using the publisher’s lookup key, ensuring that unauthorized users cannot even detect the existence of the grantee list. This adds another layer of privacy, as only the publisher and authorized grantees are aware of who has access.
  • Access Key Encryption:
    Each grantee’s access key is individually encrypted using their specific decryption key derived through the Diffie-Hellman process. This ensures that only the intended grantee can decrypt the access key and gain access to the protected content.
  • Historical Version Encryption:
    All versions of the ACT, including older ones, are protected by encryption. This means that even if a grantee’s access is revoked, the historical data they had access to remains encrypted and secure.

Content Encryption:
Finally, the actual content itself is encrypted at the chunk level. Only those who possess the correct access key (which is encrypted for each grantee) can decrypt and retrieve the content.

Key Takeaways

  • Publishers: Maintain control over your data and manage grantee access with fine-grained control using ACT. You can easily add or remove access rights and ensure your data is always protected by encryption.
  • Grantees: Access specific versions of content securely, knowing that only you have the ability to decrypt the content you’ve been granted access to.

For anyone operating in the Swarm ecosystem, the Access Control Trie (ACT) represents a critical advancement in decentralized content management, offering robust security while maintaining flexibility in access control.

If you’re interested in learning more about how ACT works or how to implement it in your Swarm nodes, have a look at the Swarm documentation.

ACT opens up endless possibilities in new type of business applications on decentralised infrastructures. If you want to know how or you already have a concept in mind have a look at our article dedicated to this topic and register your interest in a consultation with us here